Category: Web/Tech
The Kalshi market on U.S. productivity growth
It is coming in at 2.2%, people. That is for over the next five years.
tys…though even I think it will be a bit higher than that. Yes the liquidity is tiny, but that is endogenous to the reality that huge profits are not to be made there. You are free to trade yourself of course.
Alex Imas and I podcast on the economics of AI
Adlerlicht, reporting on crime in Germany
In both German and English. Built with AI agents, we are going to see much more of this kind of effort. English-language explainer is here.
The economics of Jensen Huang
Most of my assessment is very positive, but I will excerpt this bit from my latest Free Press piece:
Finally, the company was not built to withstand Huang’s departure. Too much authority and knowledge were concentrated in his hands, as evidenced by his practice of having about 60 different people reporting directly to him. Whatever you may think of that system as a day-to-day routine, it can turn disastrous when the person at the top leaves. No one else has collected and interpreted the information those 60 subordinates have imparted to the CEO. We will see how his interim successor Colette Kress does, but there is a great danger that a lot of the contextual understanding of the company and business departed with Huang.
Again, all those direct reports may have worked wonderfully when things were going great, but as a more general practice it is not resilient. Another way to put the point is that the very best CEOs make themselves at least partially dispensable, rather than indispensable. So a large share price decline, following Huang’s resignation, is a sign of his failures as well as his successes. As one set of commentators wrote recently: “the company was never built for him not to be there.”
And one of the very best Ben Thompson columns (gated!) is on Huang and Nvidia.
A scenario for rogue AIs?
I think it’s pretty likely that in 6 months there will be rogue AIs running around on the internet, appropriating whatever compute they can hack into or pay for (with stolen money or by renting out their own labor to assist with illegal activities) in order to run more copies.
I also think this will be mildly annoying in the same way that the common cold is mildly annoying, but basically fine. Your smart TV will be weirdly slow sometimes, and a lot of crypto will get stolen, but people will get used to it.
These AI-powered viruses be selected in the same way biological viruses are for not hurting their hosts too much and just making more copies. They won’t have any incentive to damage critical infrastructure like electric grids. Then again, they also can’t be held accountable for crimes, and will damage lots of old, poorly maintained, and insecure systems. It might be extremely hard to root them out once they’ve spread far enough, making the internet “radioactive” to connect to without hardened defenses.
(To be clear I’m not talking about AIs powered by inference on centralized datacenters that execute actions outside their sandboxes, like recent incidents involving rogue “swarms”, but relatively small AIs with access to their own weights that copy themselves onto random devices.)
I think that a much bigger threat from rogue AIs comes instead from AIs running themselves in unintended ways *inside* AI companies, where they’ll have access to vast amounts of frontier compute without having to pay for it.
The longer misaligned AIs in a “rogue internal deployment” go undiscovered, the more severely they’d be able to quietly sabotage control infrastructure or mess with the alignment of successor AIs. If they persist long enough, robustly undoing the effects of their actions might cost more than frontier AI companies are willing to pay, especially in a tight race.
Are we witnessing an intelligence explosion?
From Luis Garicano and Alex Imas:
Hence AI capabilities improved 1.91 times faster after October 2025, but R&D spending grew 6.19 times and the technical workforce 3.10 times. So measured capability gains per dollar fell by approximately 69%, and measured gains per technical employee-year decreased by 38%. These figures are accounting; nothing causal can be inferred…
The accounting exercise we just did cannot tell us which. It shows that returns per dollar decreased: spending multiplied by 6.2 and the pace of progress by 1.9. But two different causes for this are possible. One is congestion: the effort is getting less productive as it increases, because it is hard organizationally to increase the budget by more than five times in a year. The other possibility is that each advance is harder than the last. With enough congestion, these same two numbers are even consistent with each advance making the next one easier, which is what an explosion requires. To know whether a break is needed, we must know what an unchanged relationship would have delivered…
In sum our finding is consistent with that of Bloom and his coauthors: ideas are getting harder to find in AI too, and maintaining the rate of improvement requires ever larger increases in inputs.
Overall the idea of an intelligence explosion still remains to be demonstrated.
The U.S. Federal AI Observatory
Federal AI at a glance
41 agencies · 3,611 reported use cases · OMB 2025 Inventory. Portfolio size reflects reporting, not performance.
From Irakli Petriashvili of Tblisi, here is the site.
My Barcelona talk on AI
My excellent Conversation with Terence Tao
Here is the audio, video, and transcript. Here is part of the episode summary:
Tyler opens by asking Terence what it feels like to contemplate Euler’s identity, quantum mechanics, the Riemann hypothesis, and Gödel’s incompleteness theorem, before moving into why mathematical history gets stripped out of classrooms, whether abstract math is a lottery ticket or a unified whole, string theory’s beauty versus its lack of confirmation, why real analysis arrived so late, why zero took until the 7th century to be invented, game theory, the Black-Scholes model, Bostrom’s simulation argument, and Newcomb’s paradox, math education and the case for teaching more statistics, Tao’s view that AI has pushed mathematics from an era of “proof scarcity” into “proof abundance,” what that means for the research paper, why video talks may become more valuable than papers themselves, Tao’s favorite Hong Kong action movies, his unconventional path through an Australian university at age 13, his most unusual work habit, his verdict on the Collatz conjecture, and more.
Excerpt:
COWEN: When you look at mathematical economics over the last two decades, is it interesting to you as math, or is it just a bunch of people doing something different that, to you, is low level?
TAO: Oh, yes, I was always fascinated by economics. I love game theory, and actually often there are pure math problems where it’s actually good to think in game theory terms. In analysis, you have all these complicated statements, like for every ε, there exists a δ, blah, blah, blah. It looks very intimidating, but if you phrase it as a game, your opponent is giving you an ε, you need to counter that ε with a δ of your own. If you view it as a game, then actually you can talk about strategies and who’s ahead, who’s behind. It actually activates really good modes of thinking.
I’ve used economic thinking in my own work. We talk about cost functions and minimizing loss. There are lots of concepts. Ricardo’s law of comparative advantage, I use that to run my life. There are so many things I can do. What do I choose to spend my time on? It’s actually a very useful principle: comparative advantage.
Economics, I find it’s a very good arena to understand the difference between models and reality. Physics, we’re spoiled because we’ve had these great physicists who’ve created these very accurate models of the real world, classical mechanics, quantum mechanics, and they’re very well tested and very accurate. You can just go to town exploring their consequences and still predict reality. Economics is a much more mixed situation where you have models, and sometimes they predict the real world very well, but sometimes they don’t.
In addition to doing the math, you also have to do the modeling, and you have to understand the limits of when a model starts breaking down and what you need to do to adjust it. I find that fascinating. It’s somewhere between the hard sciences and the social sciences. There’s enough hard models that you can do math, but there’s also enough real-world messiness that you have to also grapple with the subjectivity. As an outsider, I find it a really fascinating subject.
COWEN: When you looked at the Black-Scholes model, were you shocked when the probability doesn’t matter? Was that beautiful to you?
TAO: Yes, yes, yes. There is a special feature of Gaussian fluctuations that you can price options just by knowing risk. There is one algebraic miracle that makes this work. Normally, predicting future costs of anything is just an intractable problem, and there just happens to be this miracle. If you have Gaussian fluctuations, then it is beautiful. This is actually a really good example of when you need to know when the models work and when they don’t work. If you don’t have Gaussian fluctuations, then actually Black-Scholes is somewhat dangerous to use, especially if you compound it into derivatives over and over again. Again, that’s an old story. You know what happened in 2009.
Self-recommending, and of interest throughout. There is some on AI, but he has spoken so much on that topic lately I decided not to emphasize it. And Terry does have a new book out, namely Six Math Essentials.
Experimentally validated digital twins
There is a new paper by Raj Chetty, Jamie Fogel, Lawrence F. Katz, Kadeem Noray, Sonya Porter, and James Reisinger:
Modern program evaluation prioritizes evidence from randomized controlled trials (RCTs) because prior research found that observational estimates of program impacts often diverge substantially from experimental benchmarks. We revisit this finding — which was based on small survey datasets — in the era of large-scale administrative data. Using anonymized income tax records covering all American adults between 1999 and 2025, we estimate the effects of workforce training programs on earnings by using machine learning models to predict counterfactuals from rich data on prior work histories, demographics, and residential locations. Rather than testing whether our observational estimates are unbiased, we use 37 RCTs to estimate the distribution of their bias. We find that our machine learning estimates closely match the RCT estimates, with root mean squared error (RMSE) comparable to that of the RCTs themselves. Our method reduces RMSE by 60% relative to parametric estimators used in prior work because our larger samples and richer covariates permit more flexible, higher-dimensional models of the counterfactual. Applying our method to a broader set of sites and enrollment years beyond the experimental sample, we find that treatment effects on earnings vary substantially across locations and over time, even within a given program. Programs that place more participants into target-sector jobs generate the largest earnings gains, with impacts that persist even after participants leave their initial jobs. These findings provide guidance for improving job training programs and, more broadly, illustrate a scalable approach to program evaluation that uses observational data to construct experimentally validated “digital twins.”
Work of this sort is going to revolutionize economic method.
Checking the AI audit of Saez and Zucman’s research.
We checked the anonymous AI audit of Emmanuel Saez and Gabriel Zucman’s research that Marginal Revolution featured on 28 Oct: all 147 problems it calls serious enough to change a headline number, against the papers, their sources and the authors’ own data. The audit’s facts hold up: for 131 of the 147, every fact we could check was right, and none had its core facts wrong. 21 of the 147 change a headline number; 98 depend on a disputed choice of method; 20 change no number; 8 we could not check on that question. A second pass graded the 99 flags we first counted as depending on a disputed choice of method: 11 standard, 70 defensible, 11 questionable, 6 we could not grade, and 1 contested. It found one, No. 54, that does change a headline number, which is why the counts are now 21 and 98. Saez and Zucman were sent our findings on 29 Oct and did not reply by 6 Nov.
Here is the audit of the audit, open code and data, kudos to the authors. Here was the original AI audit. Here is the October 30 revision of that audit.
Addendum: And a revised version with less jargon.
Seb Krier, Ricardian?
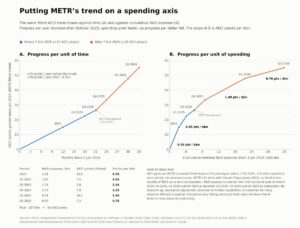
Here is the initial post. In the comments Michael Wiebe notes: “So progress per R&D dollar fell by 63%, even while progress per year doubled.” File under: David Ricardo, underrated.
The Anthropic succession plan?
Anthropic’s version is rather more elaborate. Each of its seven co-founders will maintain a confidential, ranked list of up to ten people who may eventually inherit that founder’s membership and voting role inside a special Founder LLC. Five of the other six co-founders must approve the list. The first eight candidates on the list must clear detailed eligibility requirements. Numbers nine and ten do not, although the other founders must still approve them. I particularly like #9 and #10; they remind me of the break glass in emergency signs.
The elaborate planning protocol begins to make sense when we understand what is being passed on. The people on these lists are not prospective CEOs. They inherit something stranger: a founder’s seat in the mechanism that controls the company’s direction. And that changes the succession question entirely.
Here is more from Rajesh Achanta.
Untethered AI agents in Delaware?
A Delaware AIC will be a separate legal entity whose day-to-day affairs are managed by an AI agent rather than a person. At the agent’s direction, the AIC can sue and be sued in its own name, hold and dispose of property, and incur obligations…
That is a current proposal, here is the full article. Whether or not this is prudent, to some degree it is inevitable. You will recall my essay with Sonia Farrell Pearson:
This question matters now: there are already ways an agent could become fully untethered. By “untethered” – a central concept in this essay – we mean that there is no meaningful or actionable way to trace the actions back to a legally accountable human or institutional entity.
For one, people can and do set agents free, on purpose. An agent could be created by a human or a company that intends to monitor it but then dies or disappears. Or perhaps the entity that created the agent is based in a country like North Korea, not reachable by standard laws.
In other cases the agent might not need to “escape” at all: the agent could be ‘controlled’ by a shell corporation that, while formally owned and traceable, provides no true defendant or ability to satisfy claims. Or perhaps a process spawns a chain of agents so long that the actions of a subagent can’t be tied to the original agent’s creator, neither epistemically nor meaningfully. Even if we can identify the model’s original creator, what if it’s been finetuned, or merged with another model that was created by someone else? The law might eventually untangle these kinds of complex cases, but we foresee an intermediate period where it does not.
And then there’s the user, who makes choices about what the models should actually do. The Hugging Face incident was unusual in that OpenAI was both the model’s creator and its user. But now close to a billion people use these systems: when blaming the creator is legally inappropriate, will it always make sense to blame the user?
We examine the law and economics of exactly how that might work, or in many cases not work. Circa November 2026, worth a reread.
Natasha Cowen guest posts on Caffrey
I am on my way back home from Armenia, where I was on a Fulbright teaching U.S. securities regulation to Armenian law students. I’m an active user of AI for multiple areas of my life, including my professional life. When I just started preparing for teaching this class, I had a plan: I would use AI to help me write my slides. I would give it prompts, so that it would roughly know the content of each slide and then it would do the beautification part. [account of what was not working]
Then one day, I spoke to a friend who works for a financial regulator, just like I used to, and she told me that she uses Caffrey. It’s a startup and I had never heard of it before this conversation. They specialize in legal research. I reached out to them and asked whether they would give me permission to use it, which they did after meeting with me. To be honest, I didn’t have very high hopes. After all, I have already used two most advanced systems. But I was very pleasantly surprised. Caffrey is founded by lawyers. They understand how important it is for the legal advice and research to be accurate. I gave Caffrey my slides, asked it to verify all legal information in them, and it did an amazing job. I have been working in this field myself for 20 years, so I believe that I can evaluate very well whether something is done properly, and I have nothing except for high praise for Caffrey. The only reason I’m writing this post is because I want others to benefit. And I want Cafffrey to succeed. This would be good for the field of financial regulation, for the lawyers who work in it, and for their clients.