Category: Science
AI dominates human peer reviews
We show that AI-generated article reviews are now better, by every measure we could construct, than reviews written by well-compensated human experts and judged to be of unusually high quality by journal editors and authors. We then discuss how this result may inform journal policy choices, with concerning downsides as well as potential paths to increase publication speed and quality; reduce adversarial interactions; improve the experience of editors, reviewers, authors, and readers; and advance science.
By Gary King and Steven Worthington, not even using what are now the very best models, rather based on Claude Opus 4.8. The details of the dominance, as outlined in the paper, are striking. It is not close.
On my Saez and Zucman post, I find it striking that some people are complaining all of a sudden. Yet I have been offering, citing, and linking to commentary on published papers for twenty-four years now (and every single day). Sometimes it might just be a casual offhand remark from me, whether positive or negative. Typically this is simply taken in stride. It is when you pull out the bazookas, and offer oodles of high-powered analytics, more astute than human referees, and combined with the ability to pursue follow-up inquiries, that people start getting worried. Model that.
You can pick at individual criticisms from the AIs all you want, but the most damning observation is that the errors go in the ideological direction of the authors 97% of the time. That is exactly what (the human) Phil Magness said years ago, based on an extensive canvassing of their work. Basically we already knew that was true, and the AIs confirmed the human estimate.
On our side, we have taken steps, most of all the new MR archive, to make AI analysis of our work easier. Soon you will be able to read on MR what the AIs think are our worst posts, respectively (Alex has prepared this).
In the meantime, I encourage the NSF, prize committees, universities, tenure committees, journals, and so on to do as many of their own AI-enabled audits as possible. So far the world is not jumping at this opportunity. You can model that too.
How is AI shaping economic research?
Does generative AI narrow or widen productivity gaps in research? We study the distributional effects of AI on research productivity in economics using evidence from three sources: NBER working-paper and publication records, text-based measures of LLM-assisted writing, and an original survey of 227 academic economists measuring AI use across research tasks. We first show that productivity gaps among NBER authors narrowed following ChatGPT’s release: authors without research assistants (RAs) published a larger share of papers in top-tier journals, while authors from smaller teams gained in working-paper output and publication speed. We then use the survey to examine how individual AI use affects research productivity. We find weak evidence that AI affects working-paper output on average, but there is substantial heterogeneity. Triple-difference estimates show that greater AI exposure narrows the output gap between researchers with and without RAs but widens the gap between senior and junior researchers. Selection into AI use follows a different pattern: junior researchers use AI more intensively and are more likely to use agentic tools. Thus, these differential productivity effects reflect differences in the returns to AI rather than selection into AI use. A model with diminishing returns to execution, increasing returns to conceptual capacity, and complementarity between the two explains how AI can alleviate disadvantages in research support while amplifying the returns to accumulated expertise. Over time, however, early convergence may give way to divergence as execution constraints recede and AI’s conceptual capabilities improve.
That is from Tianyu Jiang, who is this year a job market candidate from the University of Michigan. The paper is co-authored with Yuqing (Claire) Wang.
I guest host an NYT podcast with Michael Kratsios, Trump science advisor
Here is the audio, video, and transcript. Here is one excerpt:
Cowen: Talk me out of this worry: So we agree science is an ecosystem, and there’s always a temptation to want to fund the most dynamic, most productive parts of the ecosystem. And right now, that would probably be A.I.
But if you need the whole ecosystem to be working well, arguably you should be funding, at the margin, the less productive parts, which need the aid. That will sometimes be universities, but there’s plenty of other inefficient parts of our ecosystem.
So is this plan not putting more resources into the parts that are working well, but we get stuck with bottlenecks if the parts that are not working well end up with fewer resources?
Kratsios: Well, luckily, we’re not investing all of our money for the federal government into S.I. for science. It’s a portfolio approach. And obviously one ——
Cowen: But it’s a net shift toward artificial intelligence, right?
Kratsios: Well, I would argue — and I think this is a very important distinction — it’s not investing in superintelligence, it’s investing in superintelligence for science.
So the question is, I think a lot of people argue: Oh, why would the federal government want to invest more in superintelligence when billions, if not trillions, of dollars are being invested in the private sector into superintelligence? And I would agree with that statement. We shouldn’t be doing that.
The government isn’t funding how to create a next frontier model. That’s something that our great American companies are working on.
But applying those models to scientific discovery is still in its early stages. And as you know, if you think about the trend or the path by which we’ve gotten to this place with L.L.M.s — we started first with being able, essentially, to scrape the whole corpus of the internet, to use that to train a large language model.
The next chapter of that was around coding, where the model builders realized: Oh, we have really good coding data, and we can actually train these models to be good at coding. So then we had this rise of Anthropic and OpenAI Codex and all this stuff.
And I think, to me, the next chapter is around science, and the data that you need to train these large language models for science is still one that we’re working on a lot. And we were very proud to announce 190 federal data sets being made public in order to help train these science models.
But ultimately, you’re going to be applying this superintelligence to everything from material science to chemistry to math to physics, and we have to be in a position to actually leverage that.
Definitely interesting throughout, pretty much entirely we are discussing the Trump administration science plan, authored by Michael.
*This Beautiful Country*
The author is Edward Cutler and the subtitle is How Italy’s Nature Shaped its Culture and Civilisation. This is an excellent book on how “the Italy you know” has been shaped by its natural environment, such as its mountains, rivers, geology, and so on. Ever wondered why Sardinia is different? The book is good at sticking to specifics. Excerpt:
This extraordinary overlap has made Italy the continent’s botanical crossroads and one of its greatest arboreal sanctuaries. Within Europe, few countries host such a variety of native trees: at least 140 species, more than almost anywhere west of the Balkans. Some, like the Sicilian fir, Lobel’s maple and the Etna birch, are totally unique. The structure of Italy’s forests is equally diverse — dense, high-altitude canopies, open oak pastures, cork scrub and coastal maquis, each shaped by centuries of disturbance and renewal. This is the legacy of a land that sreved first as Europe’s refuge during the Ice Ages and later as its great corridor of return, where northern, eastern and African floras met and mingled in perpetual exchange.
Recommended to all those with an interest in Italy.
The archaeology tranche of Emergent Ventures
- Björn Öste is building Arkhub, an AI-powered platform that analyzes remote-sensing and other archaeological data to identify potential ancient sites in the Amazon and enable further investigation by citizen scientists.
- J. Cameron Monroe is leading the Allada Regional Archaeology Project, using lidar, remote sensing, and archaeological fieldwork to reconstruct the historical landscape of the Kingdom of Allada and strengthen cultural heritage preservation in Benin.
Previously reported grantees include:
- Benjamin Arbuckle is combining archaeology and ancient DNA analysis to reconstruct entire ecosystems of ancient cities, with the goal of understanding how human societies can thrive in balance with their environments.
- Jesse Casana, an archaeology professor at Dartmouth, is developing drone-based radar imaging methods to detect and map archaeological sites buried beneath desert sands. His work combines advanced remote-sensing technologies with efforts to preserve endangered cultural landscapes.
- Leila Character is developing drone-based imaging and AI tools to detect hidden archaeological sites, making discovery faster, cheaper, and more accessible to researchers worldwide.
- Bryce Hoenigman is developing an AI tool to help date ancient cuneiform tablets by analyzing how written symbols evolved over time, with the goal of making archaeological research faster and more accurate.
With thanks to Yonatan Ben Shimon for his generosity in support of this. We do still have funds remaining in this tranche…
New Matt Faherty study of the NSF
From the Executive Summary:
- Therefore, the NSF, NIH, and the federal government should put far more resources and effort into developing metascience. With proper metascience efforts, the NSF could run experiments on science funding reform proposals, such as shifting to a people-over-projects funding model or directly funding replication efforts, and determine which reforms will most improve NSF outcomes. The NSF’s September 2026 announcement of an Office of Metascience is a welcome step toward this goal. This report’s recommendations can help guide the office’s development, its experimental agenda, and the evaluation of its results.
- On July 21, 2026, Michael Kratsios, the director of the White House Office of Science and Technology Policy, released “Science: A New Golden Age,” a report for the President that, if fully enacted, might constitute the greatest overhaul of federal science policy since World War II. Based on my interviews and research, I strongly support most of the report’s recommendations and conclusions, and I believe the wider science community should as well.
Here is the entire study, of interest throughout. Here is an earlier Matt Faherty study on improving the NIH.
Astra Held Its Ground (Truth)
TheoPhysEval: We present a suite of 50 unpublished research-level theoretical physics problems with verifiable answers. Without AI assistance, a typical problem in our collection could be solved by a world expert in about a day or less but would take considerably longer for experts in adjacent specialties. We test the ability of off-the-shelf AI agents to tackle these problems autonomously, without human hints. When given access to tools available in a realistic setting, including the ability to search the literature and write scripts for numerical and symbolic work, the best-performing agent, GPT-6-Astra harnessed in Codex, obtains the final answers with a near-perfect accuracy of 98% at an average cost under USD 3 per problem.
Example question: Consider one-dimensional class D fermionic systems, with no microscopic symmetries other than fermion parity. Restrict to the trivial phase and to free-fermion models. Using the suspension construction, construct a two-parameter Hamiltonian corresponding to a fermion parity pump. What is the central charge of the critical theory at the diabolical point? Under free-fermion perturbations, what does the diabolical point destabilize to?
But here is the most remarkable part from one of the authors, theoretical physicist Suvrat Raju:
Our initial evaluation suggested that GPT-6-Astra’s score was in the late eighties followed closely by Opus 5.5 But, as we started to investigate the mistakes that the models might have made, the models, especially Astra, insisted that they were right and that it was the expert-supplied answers that were erroneous. When we went back to the experts it turned out, in multiple instances, that the experts found some subtle errors buried deep inside their calculations. As they revised their answers, Astra’s score started to inch up and it finally ended up with 98% (49/50).
In other words, instead, as originally intended, of the human answers serving as ground truth to test the AI, the AI answers were ground truth for testing the experts. As I commented on twitter, we are at “the fuck” level.

Okie-dokie, Casey Handmer edition
I’ve been prototyping an automated peer review project. With current models you get human level peer review for about $0.10 of tokens. For $5 you can rederive every result, check every statistical inference, and audit every paper cited in both directions.
There are about 100m papers in the scientific corpus. Most are not important. Many are sloppy. For structural reasons it’s essentially impossible to change published work, even to correct a typo.
For $500m today you can thoroughly audit every paper ever written. Every p-hacked result, every plagiarist, every fabrication, every citation club, everything.
I don’t have $500m so instead I build a tree, focusing on the 1% of papers that carry 99% of the signal, doing a cheap first pass looking for obvious problems. I can find 90% of the nonsense for a few hundred dollars of tokens.
Any guesses where the biggest surprises will be found?
Here is the link.
Predictions for economics, given AI
With math essentially being delegated to OpenAI, here’s what I predict for economics and the social sciences more generally:
The top tier of research will just become better and it will be normal human-led research where AI is used for scale (e.g. conducting qualitative interviews with relevant populations, running behavioral interventions in the field, analyzing massive text data, etc.)
Field experiments will rise in value and generally making “connections” with firms and being able to run stuff (potentially testing AI pipelines) will be in high demand
Research with administrative data will become even more valuable, but the benefits might be concentrated among some prolific authors who are allowed by the government agencies to use local models to analyze the data at scale. PhD students can probably forget about it
Economic history will have a very exciting boom and there will be an enormous race and big rewards for digitizing archives as a source to both identify new research strategies and document new descriptive facts.
Review and verification systems will become massively improved with AI assistance and it will become standard practice to do a 360 review of the paper + code + data at the *submission* stage.
Research that in principle can already be almost completely outsourced to the AI (download and analyze public data, run simple survey experiments, write theory models) is in for a big shock. This would be very bad from the perspective of researchers who depend on this “bread and butter” research, but I think this type of work will just be outsourced to public agencies who can answer their own questions without the need for “peer-reviewed” research.
All of those make sense to me.
Rising concentration for economics awards
We analyze the academic affiliations of nearly 6,000 award-winning researchers in 18 major fields in the natural sciences, engineering, and social sciences from the 1820s to the 2020s, focusing on the 1960s onward. The analysis reveals a trend of declining concentration in the institutional affiliations of award-winning researchers, shifting from a few science-strong universities in high-income countries to a more diverse set of institutions across the world. The decline in concentration is observed in all fields except one: economics. The institutional affiliations of prizewinning economists have become more concentrated over time, making economics the most concentrated field. We associate the higher concentration of prizewinning work in economics with the field’s stronger sorting by institutional prestige, its lower reliance on specialized equipment and instruments, and its assessment of findings based on a synthesis of evidence rather than on decisive experiments or proofs. We discuss the benefits and costs of this high and rising institutional concentration of prizewinning economists.
Here is more from
AI in science
Scientific progress is a key driver of economic growth and prosperity. There is great excitement- but also concerns- about the impacts of AI on science, but so far little data. We provide early insights on this from three data sources: a sample of 15 million Gemini interactions, an inventory of over 2,600 specialized AI models across disciplines, and a survey of over 600 scientists. We map these data to a new taxonomy of scientific tasks to study how scientists are using AI. Four main findings emerge. First, we find broad adoption and coverage: scientists use AI more than most other occupations. Specialized AI models have broad disciplinary coverage and are highly cited. Nearly half of the scientists surveyed report using some form of AI every day. Second, we document evidence that LLMs (proxied through Gemini usage) and specialized models act as complements—LLMs are used for general analysis, coding, and manuscript preparation, while specialized models provide domain-specific predictions, data generation and classification. Third, scientists report large productivity gains from using AI: a saving of nearly 7 hours per week, time which is primarily re-invested in more research. Finally, we show that AI is already changing the scientific process. As some stages of scientific research become easier, bottlenecks shift downstream. Scientists report an increased backlog of untested hypotheses and substantial demand for output verification. Our findings suggest that AI holds significant potential to increase scientific productivity. However, as with other sectors, its ultimate impact will be governed by complex task interdependencies and investment into the elimination of emerging bottlenecks.
That is from a new paper by Mihai Codreanu, et.al.
What should I ask Terence Tao?
Yes, I will be doing a Conversation with him. And he has a new book coming out Six Math Essentials. So what should I ask him?
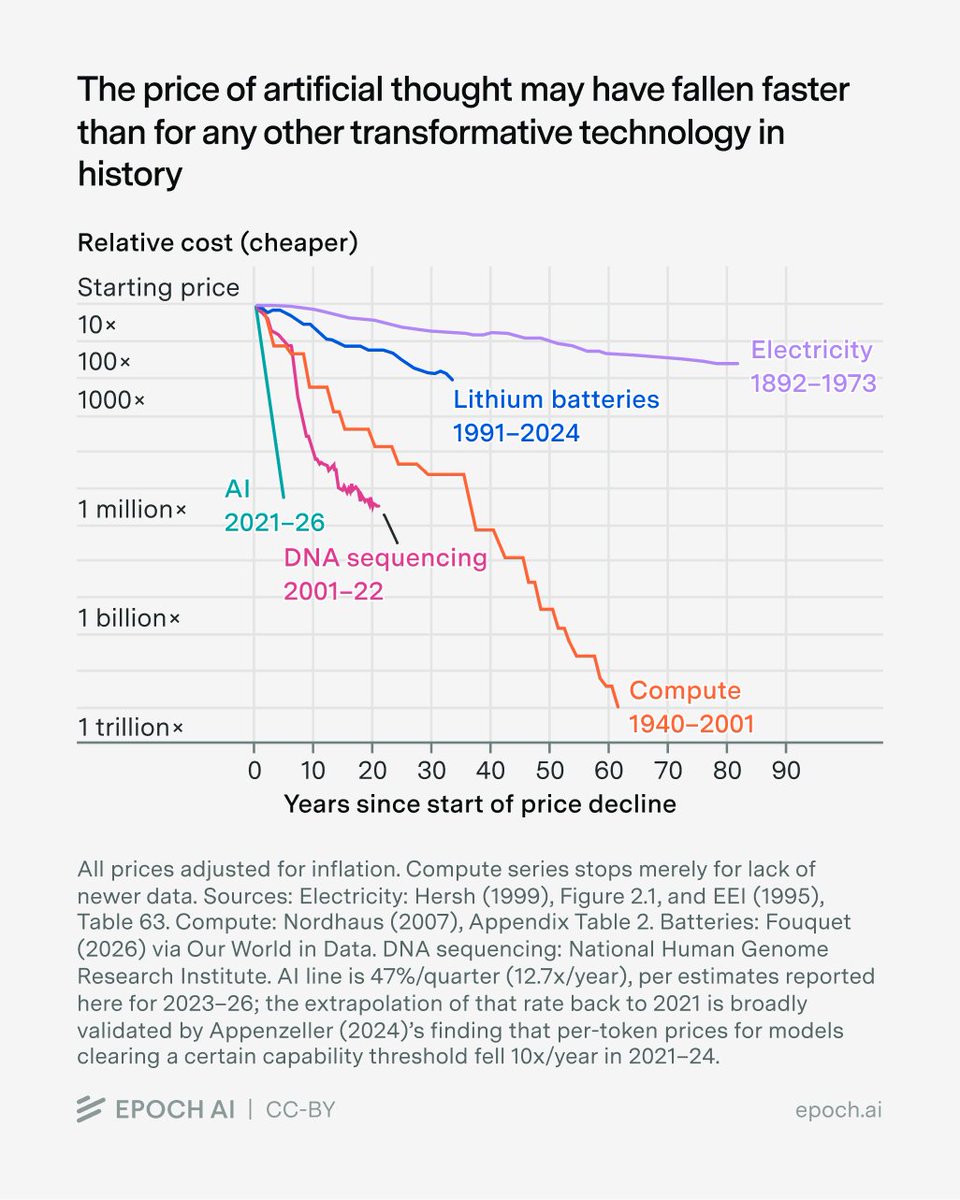
The Price of Intelligence is Falling Rapidly
An amazing Epoch AI report from Emberson and Roodman:
- Over the past three years, the cost of a given level of AI performance has fallen an average of some 47% per quarter. That is a 13-fold drop every year – a faster rate than any other transformative technology in history.
To give an example, OpenAI o3 cost about $0.30/question to attain 75% on GPQA Diamond in January 2025, while GPT-5.6 Luna attained roughly the same score for $0.0004 in mid-2026—a roughly 725-fold decline in under 18 months.
Thus, it’s not just that the models are getting smarter. A given level of intelligence is also requiring dramatically less inference expenditure. This is one reason the open-model threat is not as large as it appears: frontier models don’t merely outperform older models; they are rapidly becoming cheaper to run at any given level of performance. Smarter and cheaper.
Reimagining research papers as interactive and reliable AI agents
That is a new Nature paper by Jiacheng Miao, Joe R. Davis, Yaohui Zhang, Jonathan K. Pritchard, and James Zou. Here goes:
Here we introduce Paper2Agent, an automated framework that converts research papers into artificial intelligence (AI) agents. Paper2Agent transforms research output from passive artefacts into active systems that accelerate use and discovery. Conventional research papers require readers to understand and adapt the paper’s code, data and methods to their work, creating barriers to dissemination and reuse. Paper2Agent addresses this challenge by converting a paper into an AI agent that functions as a virtual corresponding author, exposing its manuscript, supplementary materials, datasets, code and workflows as active, agent-native knowledge rather than static text. It analyses the paper and codebase using multiple agents to construct a model context protocol (MCP) server, then generates and runs tests to refine and increase robustness of the MCP. These paper MCPs can be connected to a chat agent (such as Claude Code) to carry out complex scientific queries through natural language while invoking tools and workflows from the paper. We demonstrate Paper2Agent’s effectiveness through case studies. Paper2Agent created an agent that leveraged AlphaGenome1 to interpret genomic variants and agents based on Scanpy2 and TISSUE (transcript imputation with spatial single-cell uncertainty estimation)3 to conduct single-cell and spatial transcriptomics analyses. We validate that these agents reproduce the results of the original papers and carry out novel user queries. Paper2Agent created multiple agents that collaborate to prioritize a causal gene for psoriasis. By turning static papers into interactive AI agents, Paper2Agent introduces a paradigm for knowledge dissemination and a collaborative ecosystem of AI co-scientists.
As I have been saying for a while now, there is much more of this coming down the pike. Via Charles Klingman.
The mathematicians rebel against AI
Here is the statement, signed by Terry Tao among many other math notables, most of you probably have read it by now. I do not accept the most cynical interpretations of this proclamation. Some of you for instance may recall that I made and indeed stressed a similar point in the last chapter of my recent “generative book” on marginalism. In some near future, perhaps fewer economists will carry around marginalist insights and modes of thought in their heads, since you can just get the right answer by pressing the proverbial button on the AI.
I find this future disturbing, and not altogether pleasant for me personally, given how much personal status I have wrapped up in particular modes of economic thought. Yet I also know the Bastiat distinction between the seen and the unseen, and I expect the benefits to economic science from AI will be enormous, even if current practitioners cannot foresee most of those benefits today.
I do very much differ with at least one part of the mathematicians’ proclamation. They write: “…whether these changes ultimately benefit the field or have a destructive effect will in large part be determined by the decisions of the humans in control of this new technology.” There is no actual argument for that proposition, and I would sooner expect that the main “action variable” is how well the mathematicians adapt to the new reality. For instance there is nothing stopping the mathematics community from awarding status, pay, and promotions to people who “fill in the important blanks in math understanding,” even if an AI already has proven or disproven the underlying theorems. If that kind of work is so important, we still can do it and reward it professionally. In the meantime, I expect the funding for mathematics, and the interest in the topic, to rise considerably, at least in the medium term. All of a sudden, math matters much more than it used to, all the more so if P vs. NP happens to go the wrong way, or if the distribution of the primes turns out to be a little too predictable.
The mathematicians may not in every way enjoy being the subordinates or handmaidens of the AIs, but that is a change in status they simply will have to get used to, just as I realize AIs someday will end up as better column and blog writers than I am. I do not look to the companies — which I fully expect to “act like companies” — to somehow manage, moderate, or assuage that pending trend. It really is up to me to parlay my current intellectual portfolio into new, more AI-compatible intellectual and yes also marketing approaches. I’ve been given plenty of “legs up” along the way already, as is true for the Fields Medal winners as well, and it is up to me to figure out how to contribute in the future.
Might someone not invent/discover/prompt a way to use AIs to produce, articulate, and teach “more mathematical understanding” along the way? I get that solving famous dramatic math problems is the current commercial priority of the major AI companies. But as the AI space grows, these other paths hardly seem unlikely to me, and in fact the human mathematicians are the ones who can do the most to lead the way along those dimensions.
In this regard the current manifestation of complaints seems oddly early. “I didn’t like the first week or two of your intellectual revolution” is an accurate, and perhaps better reframed way of putting it. At which point perhaps a bit of patience is needed before anything else? These days, we all have more mathematical resources at our disposal, and so a bit of celebration is in order as well.