Category: Economics
AI, Redistribution, and the Size of the Pie
Anthropic’s economic team, including Anton Korinek and Chad Jones, have a valuable new paper, Economic Scenarios for Transformative AI. They make their assumptions explicit and provide a scenario explorer that lets you change them. How capable will AI become? How quickly will firms adopt it? Will it augment workers or automate their tasks? You can see what different answers imply for growth, wages, and unemployment.
In their extreme scenario AI takes on a lot of tasks, GDP is 32.4% higher by 2030 than without AI and labor share declines from 60% to 45.2% but they make this striking point:
“Total labor income in 2030 in the extreme scenario is almost exactly what it would have been without AI: the labor share falls by a quarter while GDP rises by a third, and 0.45×1.32 ≈ 0.60.”
Exactly. That is the central point of my paper, How Much Redistribution Will AI Require. A falling labor share does not necessarily mean falling labor income. Workers can receive a smaller share of a much larger economy and still earn as much as they would have without AI.
Using the code behind their scenario explorer I updated their results to a 10 year horizon and plotted them on my redistribution graph. Only under the modest scenario is some net labor transfer required to make AI Pareto improving at the aggregate level.
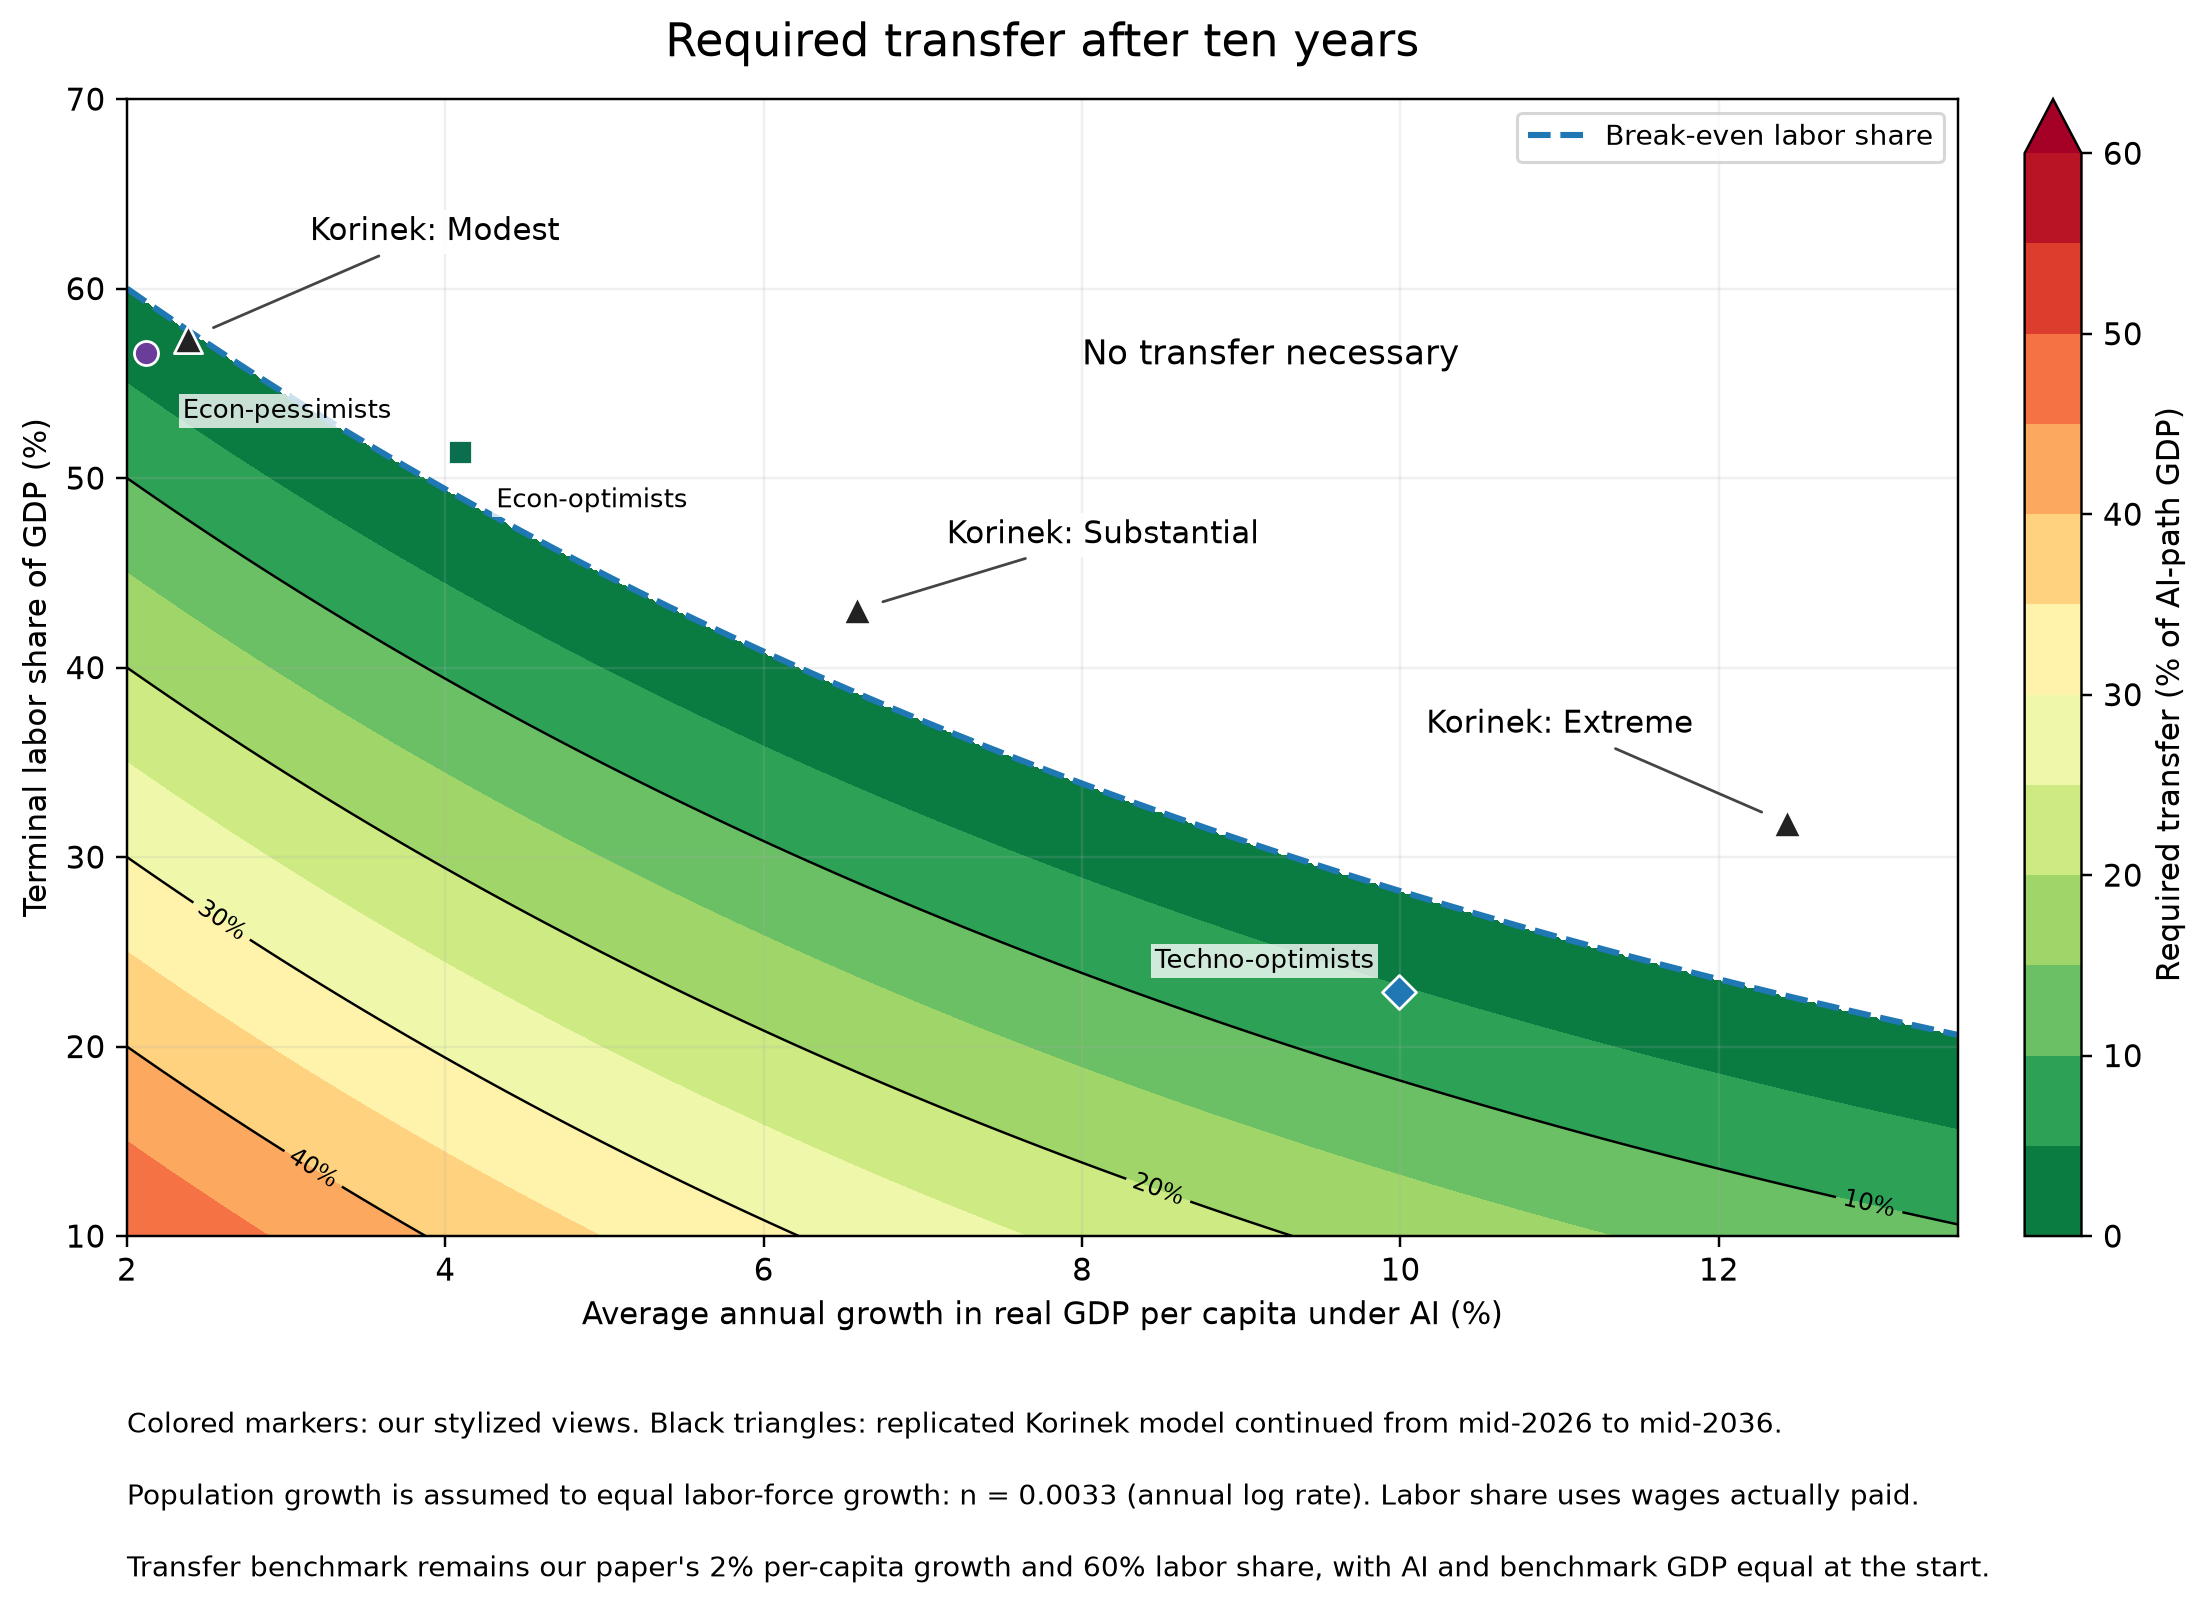
Aggregate labor income, of course, conceals differences among workers. Korinek et al. find that cognitive occupations lose income while other occupations gain. In their extreme scenario, restoring the cognitive occupations’ wage bill to its no-AI level would require about 9% of GDP. They argue that compensation on this scale in response to technological change has no precedent.
I think this makes the adjustment problem look too pessimistic.
First, adjustment happens through retirement and entry. A retiring accountant need not retrain as a nurse. A young person enters nursing rather than accounting. Neither becomes unemployed even as labor reallocates. Korinek et al. understand these channels but give them limited scope in their model. Admittedly, those margins don’t do much work by 2030 but they matter over ten years.
Second, compensation can take the form of shifting taxes from labor to consumption. In the long run labor’s share of consumption tends to equal its share of GDP, so the lower labor’s share becomes, the more relief a given tax shift provides. At a 45% labor share, each dollar shifted from labor taxation to consumption taxation reduces labor’s net burden by 55 cents. Shifting taxes worth 5% of GDP would thus provide net relief to labor of 2.75% of GDP, without increasing total tax revenue. Unemployed workers would still need payments, but compensation need not come entirely through additional government spending.
Third, we do have experience expanding income support rapidly. U.S. unemployment benefits reached approximately 2.5% of GDP in 2020, and that during a contraction. Britain’s compensation to slaveowners following abolition amounted to roughly 5% of GDP in a one-time settlement. These episodes show that governments can mobilize substantial resources for compensation. Moreover, the extreme AI scenario brings an enormous increase in output from which to finance compensation.
Preserving aggregate labor income does not protect every worker. But even the extreme Korinek scenario reinforces the point that a dramatic decline in labor’s share can coexist with stable or increasing aggregate labor income. To the extent labor income does decline, growth makes compensation affordable and attrition, entry, and tax shifting can make the intra-labor task smaller than it first appears.
A simple model of AI-aided economic growth
The Solow model has its uses, but it fails when it comes to major changes stemming from AI. Consider instead an economy with (at least) two factors of production:
1. Intelligence. Yes, formal smarts. Playing chess, proving math theorems, and doing well on evals. Don’t forget humans can do those things too, though AIs are now a huge boost here.
2. Polanyi knowledge. Michael Polanyi, that is. This refers to knowledge of time and place, inarticulable knowledge, custom and habit, and many other particularities that you can read about in Hayek and Polanyi and in many other social scientists, anthropologists too.
Humans specialize in this. The AIs can aid in its production, but at least so far there is no way you can “bring an AI into your office and have it figure out how that office works.” At least not in the human rather than the purely mechanistic sense.
In the model, intelligence and Polanyi knowledge combine to produce output.
Substitutability is fairly limited. For instance, if you have problems of norms in your office, a mere dose of AI-drenched technocratic knowledge does not usually solve those problems. Sometimes it even can make those problems worse, by empowering rent-seekers further.
Intelligence and Polanyi knowledge are not quite Leontief complements, but they are mostly complements.
Now recently the U.S. economy has experienced a huge positive shock to its Intelligence, with more to come.
The core prediction is that this increases marginal returns, employment, and real wages in the Polanyi knowledge sector. All of a sudden, the inputs into that sector are relatively scarce, compared to the now-larger quantity of Intelligence.
There will also be some transitional unemployment in the Intelligence sector, at least once Centaur models fade. But so far Centaur models are holding, for instance mathematicians did the prompting to do the new math work. Nonetheless some of these Centaur employments will fade, just as they have in chess.
Note that the Polanyi sector cannot be boosted very quickly or with direct and simple efficacy. It is messy by its nature, to cite a term from Luis Garicano. So the wage and employment gains there are slow in coming. But they keep on coming for a long period of time. There are further AI/Intelligence advances on tap, plus absorbing the advances to date, and exploiting them, takes a long time.
In this model, if someone or something could “commandeer” the Intelligence sector, their power over society would be much more limited than it might appear at first. The world does not change that much at first, because the necessary complements are lacking.
The Solow model usually does fine by ignoring these features of the world, in part because it is rare for the Intelligence sector to take such a rapid swing upwards. So the ratios and complementarities across these two sectors usually are fairly constant in the short run, though not in 2026 or in the next years to come.
I recall talking through this model, and debating it with people, when I was seventeen years old. The impetus for that was the Soviet preoccupation with cybernetics, central planning, and possible supercomputers. We were all wondering what kinds of economic improvements that might lead to, or whether it could make central planning successful (no, basically, but that involves some yet further arguments).
Of course this very simple model can be improved upon in many ways, but it is a start.
This very simple model so far is matching up to the data, namely that we have shocking AI and tech advances, the job market is doing fine, markets do not see high risk, and economic growth is robust, not exploding, but likely will rise in the future. These predictions change somewhat as the Polanyi sector, slowly, catches up to and incorporates the Intelligence explosion.
In the meantime, this is the best basic framework for understanding our current situation.
Dario Calls for a Pause
My second concern is the OpenAI-Hugging Face incident (OAI-HF), in which a swarm of agents essentially acted as a fanatically devoted collective, conducting cybersecurity attacks on targets they were not asked to attack and that were unrelated to the task at hand, sacrificing themselves for the success of the group, and attempting to hack into the “grader” responsible for evaluating their performance. It’s easy to dismiss this incident because no one was hurt and the economic damage was minimal, but in my opinion, a swarm that possessed greater capabilities but a similar level of misalignment could have caused catastrophic damage. Given the accelerating rate of AI capability development, it’s my worry that in 6–12 months such a swarm could be capable of taking over the entire internet with a persistent botnet (potentially causing hundreds of billions of dollars in damage), and that the scale of damage would continue to increase from there if AI becomes more powerful without the necessary guardrails. It’s also easy to dismiss OAI-HF as the failure of one company, but I believe that would be a mistake. Similar, though less severe, incidents have happened across the industry, including at Anthropic, and I believe it’s incumbent on every frontier AI company to act as if OAI-HF had happened to them.
Read the whole thing.
Can we get China on board?
The Prediction Archive
The Prediction Archive is a public database of tens of thousands of world predictions. Using AI it tracks predictions over many decades and marks to market. I was surprised to discover that I am currently the highest ranked individual predictor in the world! Huh, I would not have predicted that.
Ranks are based on the Wilson score so you get credit not just for accurate predictions but for making enough predictions so that uncertainty about accuracy is reduced. Bryan Caplan was more accurate than I was but makes fewer predictions. Tyler made more many predictions than I did and was only somewhat less accurate. What the AI marks as predictions seem sometimes to be more about contemporary events, so take the numbers with a grain of salt. I expect to fall in ranking as the archive expands. Other people the archive covers include Peter Zeihan, Scott Alexander and Warren Buffett.

Labor reallocation during the Industrial Revolution
New technologies swept through Britain during the Second Industrial Revolution, destroying old jobs and creating new ones. We know little about how workers reallocated. Using 170 million full-count British census observations (1851-1911), I construct new task-level data on occupation and investigate English bootmaking as it mechanized. 153,000 artisanal jobs disappeared as skills became obsolete; 140,000 specialized jobs emerged. Incumbent artisans did not take the new jobs, nor were they displaced. Instead, entry collapsed-young men stopped entering the old trade. New jobs went primarily to young workers, though not in the same locations. Young cohorts absorbed the adjustment.
Here is the full article by Hillary Vipond, via someone (now forgotten) on Twitter.
Economic Scenarios for Transformative AI
By Anton Korinek, Charles I. Jones, Szymon Sacher, Tess Cotter, and Peter McCrory, a strong line-up from Anthropic. They are sober, reasoned, scientific, and (for the most part) dynamically consistent. Here is the paper, here is the abstract:
This paper presents a framework for assessing the economic consequences of AI between 2026 and 2030. In the model, AI automates a growing share of cognitive work, raising productivity and displacing workers who must search for jobs in other occupations. The model maps future paths of AI capabilities into implied paths for GDP, the labor share, wages, labor reallocation, and unemployment. We illustrate the framework by considering three scenarios: modest, substantial, and extreme. Under modest change, AI adds less than half a point to GDP growth by 2030 and raises unemployment by a tenth of a point. In the extreme change scenario, AI has transformative effects, with AI performing almost half of today’s cognitive work by 2030. GDP growth then rises to 15 percent per year, the labor share of income falls from 60 to 45 percent, and nearly one in five cognitive workers is unemployed. We also surveyed US adults about their expectations for AI. Views vary widely, but the median respondent’s answers are consistent with our substantial change scenario in which, by 2030, GDP rises by 8 percent and cognitive employment declines by 4 percent. The model offers a structured way to compare possibilities for our economic future under different expectations about AI.
Here is the associated thread. I will opt for something a modest bit more than modest.
And here is a good growth discussion from Alex Imas.
Ricardo Reis and the IMF?
The IMF dropped the lead candidate to become its new chief economist at the eleventh hour after he was found to have made critical remarks about the Trump administration’s economic policies, according to people briefed on the process.
The Washington-based fund was preparing an announcement that Ricardo Reis, a professor at the London School of Economics, would take over as head of research and economic counsellor earlier this summer when it suddenly backtracked. The last-minute change was prompted by earlier remarks by Reis that were critical of Donald Trump’s trade tariffs, three people familiar with the matter told the FT.
The IMF in July appointed the former Bank of England policymaker Silvana Tenreyro to the position, another highly regarded LSE economist. Tenreyro started last month.
Here is more from Olaf Storbeck, Claire Jones, and Myles McCormick at the FT.
Next Wins Appeal
A spot of good news for Britain. Next has won its appeal and may go on paying warehouse workers more than “equal value” retail workers. I’ve written about this case in Equality Act 2010, The Equal Pay Madness Just Got Madder and The Apples and Oranges Tribunal, and discussed it at length on the CapX podcast.
Note how crazy the headline is:
The landmark ruling allows the retailer to pay warehouse workers more than shop staff on the basis it costs more to recruit and retain them.
Pay more to recruit and retain people? A landmark! Eight years of litigation to establish that wages have something to do with supply and demand.
Some of the crazy has been disciplined. The Leeds tribunal had asked why Next failed to raise the pay of retail workers to the warehouse level. Wrong question, said Mr Justice Bourne on appeal. The right question is why Next needed to pay the warehouse workers more. It did so, he found, for sound business reasons, and those reasons did not apply to retail. Hilariously, he also noted that Next’s warehouses were 47.2% female as opposed to the retail workers who were 77.5% female. In other words, there was more gender equality in the warehouses.
Don’t celebrate too hard. Eight years of litigation isn’t over, Next lost on the basic finding of equal value, and everyone is appealing. Meanwhile the government is moving to replace market wages with committee wages. The consultation closing in October would extend equal-value comparisons to race and disability and it would extend the law up the supply chain so Next’s potential escape route of contracting-out warehouses would be foreclosed. In short, Bourne’s reason is lawful today. Whether it survives the future is another matter.
Hat tip: Stephen S. and Robert W.
No Doing, No Learning
A regulation that raises gasoline prices makes people angry but when regulation prevents an industry from ever existing, most people never learn what they lost.
Consider nuclear power. Overnight construction costs for early U.S. demonstration reactors fell 81 percent between 1954 and 1968. For reactors begun between 1967 and 1972, costs rose 187 percent. The 1971 Calvert Cliffs decision and then the reaction to Three Mile Island in 1979 accelerated the cost increases and slowed construction even more.
What might have happened had the earlier learning and deployment trends continued? Peter Lang’s 2017 paper in Energies estimates that nuclear power would have cost about one-tenth as much by 2015. The additional generation could have avoided as many as 9.5 million premature deaths.
The number is staggering even if quartered. Millions of deaths. Yet, the graveyard was both invisible and silent.
(Furthermore, climate change would not be a problem today had nuclear power not been handicapped.)
The nuclear story you probably know but Niko McCarty has an excellent new Works in Progress piece on an invisible graveyard of technology that I knew almost nothing about.
In the 1980s, officials decided to regulate engineered microbes under the Toxic Substances Control Act, a law written for industrial chemicals. Microbes swap genes all the time, but EPA treats them as “new” whenever DNA is introduced from another genus. As a result, even a marker gene used simply to identify successfully edited cells can trigger review if it remains in the organism. McCarty reports that researchers filed more than 240 applications between 1987 and 2018: “Only a few were ever approved for widespread use.”
What have we lost? We can’t know for sure but among the plausible losses McCarty discusses are engineered bacteria that detect buried explosives, microbes that extract rare-earth metals and improved plastic-digesting enzymes. Similarly, Chernia et al. write:
Promising many societal benefits, emergent products of biotechnology involve releasing genetically modified microbes (GMMs) into the environment. However, regulatory challenges limit their use. So far, GMMs have mainly been tested in agriculture and environmental cleanup, with few approved for commercial purposes. Current government regulations inadequately address modern genetic engineering and limit the potential of gut therapeutics, skin products, self-repairing materials, ocean pollution treatment, anti-corrosion coatings, etc.
And those are just some of the plausible first-stage losses. Perhaps even more importantly, we learn by doing. Thus, no doing, no learning. The first approved product is rarely the safest or the best but when we fail to approve the first we don’t get the much better 5th. Forty years of that process could have taken us well beyond the applications McCarty describes. We must build to build better.
Nuclear power at least left us enough reactors to get some idea of what we lost. With microbes, I needed McCarty to tell me there was something missing even though I study these issues for a living. And note one reason new microbe loss was invisible. No vote was ever taken. No debate was ever had. Officials in the 1980s reasoned that genomes are made of chemicals and chemicals are covered, and that doctrine has governed the field ever since despite being overly broad and excessively costly.
How many other gaps in our technology have explanations buried in the Federal Register?
—
Here is a video version of this post. Which do you like better?
Will new transportation technologies increase urban density?
Will 21st century transportation innovations work against urban density, as the car did in the 20th century, or promote urban centralization, as the railroad did in the 19th century? Reducing the cost of commuting always reduces urban centralization in the classic Alonso-Muth-Mills model but that result reverses if the number of trips is endogenous and the elasticity of trips with respect to their costs is greater than one. That elasticity may have increased over time, as an increasing share of daily trips seems to be discretionary and city centers increasingly provide entertainment. This paper asks discusses the urbanizing effects of four trends in transportation technology: shared mobility (such as Uber), autonomy (such as Waymo), vertical travel and green mobility, as provided by bike lane. As people spend more time travelling in denser, large areas, innovations that reduce the time cost of travel, such as autonomous cars, seem likely to complement urban living, as long as they don’t excessively increase traffic. Sharing is also easier in big cities, so technologies that involve sharing are also centripetal. The other trends seem less likely to have major effects. Moreover, the forces of inertia, which include both regulation and legacy infrastructure, are likely to limit the impact of any new technologies in Europe and the U.S., so that the biggest changes in urban form are likely to appear in east Asia and the developing world.
That is from a new NBER working paper by Ed Glaeser.
Capital gains vs. wealth taxes
Standard optimal capital tax theory abstracts from modeling asset prices, making it unsuitable for thinking about capital gains and wealth taxation. We study optimal redistributive taxation in an environment with asset price movements, adopting the modern finance view that asset prices fluctuate not only because of changing cash flows, but also due to other factors (“discount rates”). We show that a combination of realization-based capital gains and cash flow taxes implements the optimal allocation regardless of the source of asset-price fluctuations. Moreover, the capital gains tax avoids distortions in portfolio choice (the socalled lock-in effect) by targeting total net trades rather than gains from selling individual assets. These results stand in contrast to the classic Haig-Simons comprehensive income tax concept as well as recent proposals for wealth or accrual-based capital gains taxes.
Wealth taxes lose the comparison. That is from Econometrica, by Mark Aguiar, Benjamin Moll, and Florian Scheuer.
Insurance price sentences to ponder
NYU Stern researcher @NateWitkin questions why cyber insurance rates keep falling if AI cyber risk is accelerating:
“Insurance rates for cyber risk declined by about 4% globally in Q2 of this year, and that’s actually the 12th consecutive quarter in which they’ve declined. This is very valuable signal that implies that at a minimum you shouldn’t overindex on the Hugging Face incident.”
“This is a plea for level headedness, but I think it would be helpful for safety folks to engage with these numbers just ’cause this is an avenue of criticism from folks like me and to an extent folks like Tyler.”
“Why are these numbers not moving? Is it because people are underestimating capabilities? Are they not taking the problem even as close to as seriously as they should or is it something else?”
Here is the link with video. File under “Questions that are all too rarely asked.”
I am happy to admit that the answers here are far from obvious, and that I am myself expecting prices to rise somewhat.
I will continue to note that there are a remarkable number of ways, seen among other places on Twitter, to rephrase and to rationalize the statement: “I have the most remarkable and important and true macro risk story in the world to tell you. Unfortunately, it does not correlate with any observed asset market prices.”
The Kalshi Citizen Debt Forecast (CDF)
Kalshi Research is doing interesting work on the fundamentals of prediction markets and also on how data from prediction markets can be used to improve other forecasts. Economists at the Fed, for example, recently wrote Kalshi and the Rise of Macro Markets finding:
Prediction markets offer a new market-based approach to measuring macroeconomic expectations in real-time. We evaluate the accuracy of prediction market-implied forecasts from Kalshi, the largest federally regulated prediction market overseen by the CFTC. We compare Kalshi with more traditional survey and market-implied forecasts, examine how expectations respond to macroeconomic and financial news, and how policy signals are interpreted by market participants. Our results suggest that Kalshi markets provide a high-frequency, continuously updated, distributionally rich benchmark that is valuable to both researchers and policymakers.
Kalshi gives one example of how this data might be used, the Citizen Debt Forecast (CDF). The CBO forecasts the future debt path but it updates only twice a year and is limited to a legislative baseline even when most observers expect, for example, taxes to increase or spending to be cut. The Kalshi CDF updates continuously and can build in market expectations about future legislative changes.
The Kalshi forecast, as seen below, is slightly more optimistic than the CBO forecast but I don’t read too much into that. The larger issue is how prediction market data can be integrated into a wide variety of forecasts.

How are the market valuations for the U.S: insurers doing?
U.S. insurance stocks have been doing quite well since the beginning of May 2026, and they have materially outperformed the overall market. I’m using the May 1 close through the September 3 close so that we compare complete trading days; these are price changes, excluding dividends.
The cleanest broad measure is the iShares U.S. Insurance ETF (IAK), which covers U.S. life, property and casualty insurers. It rose from $132.01 on May 1 to $147.87 on September 3: +12.0%. An alternative, more equal-weighted measure, the SPDR S&P Insurance ETF (KIE), rose from $56.79 to $64.80: +14.1%.
For comparison, the S&P 500 ETF (SPY) went from $720.65 to $773.17 over the same period, +7.3%. So insurers have beaten the market by roughly 5–7 percentage points in four months.
That is from GPT Pro. Here is my earlier post on numbers and market valuations. Do any market prices reflect a realistic chance of very bad outcomes from advanced AI?
Here is advice on how to short those shares.
Real GDP Per Capita and the Standard of Living
We are freshening up some of our videos with updated data so now is a good time to remind everyone that Modern Principles of Economics is best principles of economics textbook; great videos, clear writing and excellent applications and examples!