Category: Economics
How Much Redistribution Will AI Require?
How much redistribution will AI require? A common scenario is that AI raises output enormously, but labor’s share of income collapses. GDP per capita goes up but workers get poorer, and making workers whole requires massive redistribution. In my latest paper, I run the numbers and conclude that this is probably incorrect.
The idea is simple. Labor income is GDP multiplied by labor’s share of GDP. What matters is the product. A smaller share of a much larger economy can still mean more income for labor. If the pie is growing, labor’s slice of the pie can shrink even as labor income rises.
Suppose that without AI, real GDP per capita grows at 2 percent a year and labor receives 60 percent of GDP. Now look ten years ahead. What is required to keep labor’s income growing at the same or higher rate?
If AI raises growth to 5 percent a year, GDP after ten years will be about 34 percent larger than on the no-AI path. Labor’s share can fall from 60 percent to about 45 percent and workers, in aggregate, will still have exactly as much real income as they would have had without AI.
If AI raises growth to 10 percent a year—the kind of number Satya Nadella and Dario Amodei talk about—GDP after ten years will be more than twice as large relative to the no-AI path. Labor’s share can then fall all the way to 28 percent without reducing aggregate labor income. Twenty-eight percent of an economy that has more than doubled is about the same as sixty percent of the smaller economy.
The figure shows how much redistribution is required after 10 years under a variety of scenarios.
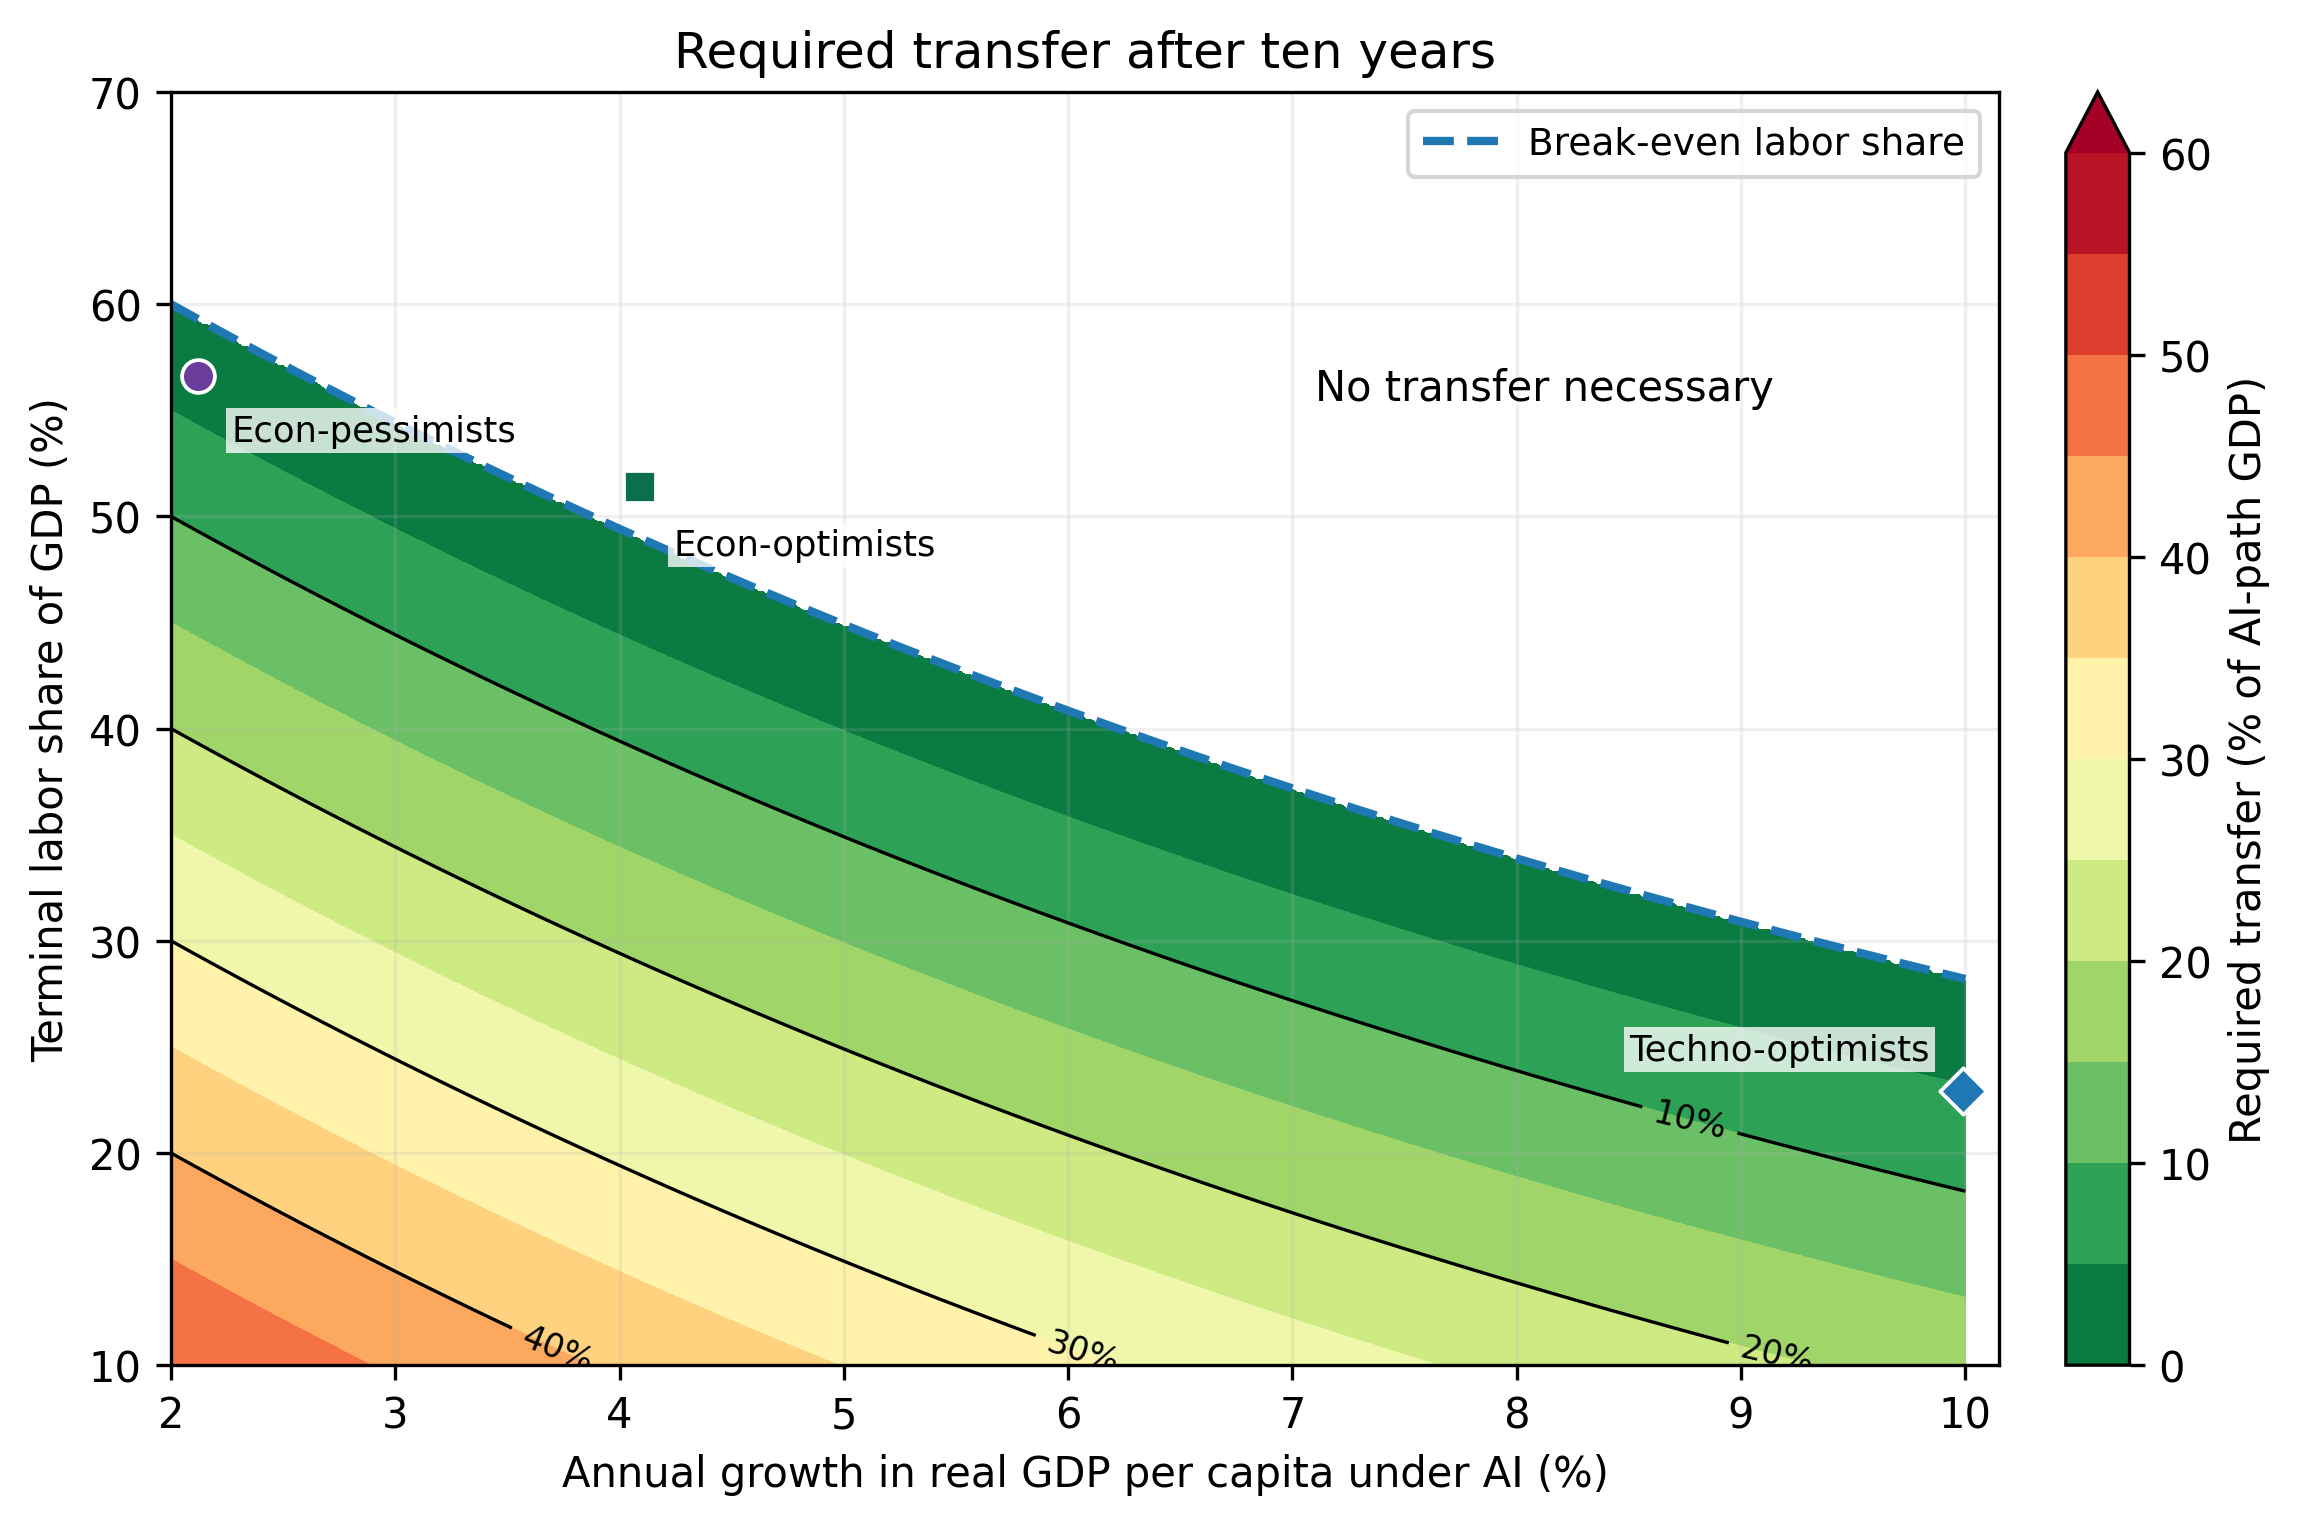
The white region above the dashed line requires no transfer. Which region are we headed for? Consider three “stylized” views.
The econ-pessimist, following Acemoglu, thinks AI displaces some but relatively few tasks because AI simply is not productive enough to replace much labor profitably. Growth is only 2.1 percent and labor’s share falls to 56.6 percent, although particular industries may still get hammered. The required transfer is 2.7 percent of GDP.
The econ-optimist, in the spirit of Tyler, myself, and Kevin Bryan, thinks automation also creates complementarities and new tasks for humans. Growth rises to 4.1 percent, labor’s share is 51.4 percent, and both labor and capital gain without any transfer.
The techno-optimist, following Amodei, has the superficially scariest labor-market scenario: three-quarters of labor income is displaced and labor’s share falls to just 22.9 percent. But productivity growth is also enormous, producing 10 percent annual growth. The transfer needed to keep labor as a whole on its no-AI path is only 5.3 percent of GDP.
That last calculation is the one I find most surprising. You can have something close to the techno-capitalist dystopia in terms of factor shares—labor gets less than a quarter of GDP—and still have a manageable redistribution problem because GDP has gotten so much larger.
Moreover, a transfer equal to 5 percent of GDP need not mean raising taxes by 5 percent of GDP. We already tax labor a lot. We could thus compensate labor by shifting from labor taxes to other taxes. Federal payroll taxes alone are about 6 percent of GDP. Cutting payroll taxes and replacing them with a broad consumption tax that also reaches spending from capital income and accumulated wealth is a form of labor compensation (plus we could have some transfers to those with no labor income).
Of course, keeping aggregate labor income whole does not mean every worker does well. There could still be enormous churn, big losses in particular occupations, and painful transitions.
Nevertheless, the larger point is that labor’s share by itself tells us surprisingly little about the distributional consequences of AI. We also need to know how much the economy grows.
If AI produces ordinary growth while dramatically reducing labor’s share, redistribution becomes very difficult. But if AI really does produce 5, 10, or 15 percent annual growth, the compensation problem is surprisingly modest even with very large displacement. As I have emphasized elsewhere, we could cut the working week in half under many scenarios and increase hourly wages above the non-AI benchmark and make both capital and labor better off.
Growth is a good problem to have.
The College Wage Premium in the Generative AI Era
After expanding for four decades, the U.S. college wage premium is experiencing a sustained contraction, dropping sharply from 0.626 in 2022 to 0.575 in 2026. Using Current Population Survey Outgoing Rotation Group data through 2026, we show that standard market-clearing supply-and demand accounting implies an unprecedented drop in relative demand for college labor-the first sustained negative relative demand growth in a series spanning back to 1914. Linking individual wage data to task-based generative AI exposure, we document that post-2022 wage growth slowed disproportionately in high-exposure occupations, which employ a disproportionate share of college graduates. By 2026, going from zero occupational AI exposure to full exposure had a negative effect on wages of -0.086. Combined with the college-non-college exposure gap, this mechanism accounts for roughly 28 percent of the total drop in the college wage premium from 2022 to 2026. While noncausal, these patterns indicate that task displacement in AI-exposed white-collar occupations plays a quantitatively meaningful role in the recent compression of the aggregate skill premium.
I do not see AI as driving these changes, but an interesting result nonetheless, from José Azar, Mireia Gine, and Javier Sanz-Espín. Via Anecdotal.
Who values democracy?
This paper examines the conventional view that redistribution is central to the democratization process using data from stock markets. Consistent with this view, democratizations have a large, negative impact on asset valuations driven by a rise in redistribution risk. Across 90 countries over 200 years, risk premia are substantially elevated— similar in magnitude to financial crises—prior to and during democratizations. A shift in Catholic church doctrine in support of democracy provides causal evidence that democratizations increase risk premia. Successful democratizations lead to substantial redistribution: the size of the public sector grows, income inequality falls, and the labor share of income rises. An extended version of the canonical redistribution-based model of democratization that includes asset prices can quantitatively explain these effects. Reductions in inequality and increased taxes explain approximately half of the results. The rest comes from greater economic competition and equality in government spending. The model also explains the negligible asset pricing response to autocratizations. Neither an increase in macroeconomic risk nor generic political risk can explain the results.
That is by Max Miller, now published in the JPE, ungated copy here.
More optimistic results on AI and job markets
Here is a good Jon Hartley thread. Here is the paper, with Jolevski, Melo, and Moore. From Jon’s thread: “Generative AI adoption is widespread, but substantial aggregate labor-market disruption is not yet visible. Workers nevertheless perceive substantial displacement risk, especially when firsthand use reveals that AI can perform key tasks for their job.” And again here is Alex’s post from yesterday.
AI and Employment: So Far, So Good
In September 2023, the Census Bureau added questions about AI to its Business Trends and Outlook Survey. Census asked hundreds of thousands of businesses whether they had used AI in the previous two weeks to produce goods and services. At that time, 3.7% said yes; by late 2025 the figure had reached about 10%. (In November 2025 Census broadened the question to ask about AI use in any business function, producing a jump in measured adoption to about 18%.)
Twice the Bureau has asked a key question:
In the last six months, how did the use of Artificial Intelligence affect this business’s total employment?
In Dec. 2023 to Feb 24, when ~5% of firms were using AI the answers were 2.8% increased, 2.6% decreased and 94.6% reported no change. Two years later, in the Nov 2025–Feb 2026 supplement, the answers were: 2.3% increased, 2.0% decreased, and 95.7% reported no change. The answers were similar by firm size.
Some sectors reported more action. Information is the one sector where fewer than 92% report no change. But overall, almost all firms report no change and of those reporting change it’s about evenly divided between increasing and decreasing employment.

The supplement also asked about tasks. Among firms using AI, 44% say it supplemented or enhanced work an employee already does. Ten percent say it performed a task an employee used to do. Eleven percent say it introduced a task no one had been doing.
Among those using generative AI, 85% of firms cited writing or editing documents and email as the biggest uses, half cite searching for information, 45% summarizing documents, and 13% coding. Sixty-four percent of adopters say they changed nothing about the business in order to use AI, 15% trained existing staff, another 15% built new workflows, and just over one percent hired anyone with AI skills.
Among firms where AI has taken over some employee tasks, the degree of substitution is growing. The share reporting that AI took over “a large number” of tasks rose from 2.4% to 7.1%, while the share reporting “a moderate number” rose from 13% to 22%. But this group is still small: only about a tenth of AI adopters, who themselves make up about a fifth of firms.
I have reported firm-weighted estimates but employment-weighting gives essentially the same result. Thus, we have unusually direct evidence from a very large sample, and it says that the overwhelming majority of firms using AI do not yet report any effect on total employment. Very consistent with what Tyler and I said in our talk to OpenAI.
I used Fable and ChatGPT Sol in producing this post.
Anthropomorphizing AI?
I am very much opposed to the view that the AIs are sentient, or might be sentient. I view that as a category error, and the chances of it being true are vanishingly small. Nonetheless I largely side with Roon when he writes:
there are some number of bad abstractions in anthropomorphizing ai intents but there are at this point more dangers from avoiding anthropomorphism at all costs. if you have a mental picture of guys living in computers, it’ll likely prepare you for the future better than otherwise
While I am not a Friedmanite in economic methodology per se, I have lived with that perspective for a long time and have no trouble grasping it or working with it, same goes for Alex T. None of this strikes me as weird or unacceptable. Though be very, very careful when speaking with others, whether it be the less informed public or the more informed insiders who often come down with AI psychosis. So insofar as this discourse is public, pragmatism may militate against this approach, even though it is methodologically defensible. It depend on how psychologically robust your audience is?
We also need to do more work figuring out how the AIs might differ from humans. Roon adds:
there are important ways in which ai psychology diverges from human psychology after lots of RL; the misaligned models are obsessed with the Scorer, the clearly “shattered” nature of personas (a normally helpful model can become deeply misaligned in certain domains)
And:
persona selection is clearly far less clean than many people thought earlier this year. it is not alignment by default and what kind of object a “persona” is is very much up for debate and study
The AIs also stand a higher chance of becoming very wacky as the discourse proceeds? Exactly how much is that true for humans?…I am not sure.)
There is much more to be done in this direction, and it is one of the most important things you can be working on. These investigations also do not need to be “owned” by any single field or discipline, so dig right in.
Scholar Data
In our paper, A Skeptical View of the National Science Foundation’s Role in Economic Research, Tyler and I point out that if the NSF is doing what it should, it ought to be doing very different things than other funders:
Public goods theory tells us that the National Science Foundation should support activities that are especially hard to support through traditional university, philanthropic, and private-sector sources. This insight suggests a simple test: to the extent that the NSF allocates funds to genuine public goods as opposed to subsidies on the margin, we ought to see a large difference in the kinds of projects the NSF supports compared to what the “market” sector supports. But what stands out from lists of prominent NSF grants (like the one provided by Moffitt in this symposium) is how similar they look to lists of “good” research produced by today’s status quo. If we take public goods theory seriously, what areas of economics should be supported?
We suggest replication studies and support for producing public datasets. Which brings me to Scholar Data, a neat new project that won NIH’s competition to create a data-sharing index. Scholar data creates an S-Index, like an H-Index for papers, but instead the S-Index measures a dataset’s ease of access, citations and other mentions. The point is to create a metric to reward the creation of a public good:
Researchers invest years collecting and sharing datasets that underpin reproducibility, transparency, and discovery across every field. Without shared data, findings can’t be verified, built upon, or trusted. And yet, the metrics that define academic careers, such as citations, h-index, and impact factor, only count publications. Data sharing goes unrecognized and unrewarded.
This creates a broken incentive: researchers are expected to share data, but get no credit for doing so. The result is that data sharing is treated as a chore rather than a contribution.
Scholar Data and the S-index are aimed at fixing this. By measuring how impactful your datasets are, the S-index gives data sharing the same visibility and recognition as publishing, turning it from an obligation into a career asset.
Bravo! Your dataset may already be catalogued. You can get credit at ScholarData.
A Big Bet on Explosive AI-Driven Growth
Wow! The excellent Ben Moll has put together a high-stakes bet on US economic growth.
A bet on near-term explosive AI-driven growth: whether U.S. real GDP per capita will grow by at least 15% within a single year (measured relative to prior peak) by the end of 2033. Agreed on X, 15–16 August 2026. This document summarizes the agreed terms.
1. Parties and stakes
Fast-growth side (wins if the growth condition in Section 2 is met):
● William MacAskill https://www.williammacaskill.com/ — $10,000
● Samuel Albanie https://samuelalbanie.com/ — $25,000
● Tom Cohen https://x.com/tomcohen — $25,000
● Total: $60,000
No-fast-growth side (wins otherwise):
● Benjamin Moll http://benjaminmoll.com/ — $40,000
● Andrew Ho https://andrewho.xyz/ — $200,000
● Total: $240,000Odds: 4:1 — every $1 staked by the fast-growth side is matched by $4 from the no-fast-growth
side. Implied probability of the fast-growth scenario: 20%.
I’m known for quipping that a bet is a tax on bullshit but I don’t think either side is BSing. We have a genuine and important disagreement. I’d side with Moll, for what it is worth.
The Antitrust Academy
The Antitrust Academy is an online platform hosting hundreds of videos comprising a complete course in antitrust law and economics. Teachers include Judge Douglas Ginsburg, Jon Klick, Joshua Wright and others. I am an advisor. A great resource whether you are learning this material for the first time or need to brush up on some legal or economic doctrines.
Important results on economic mobility
We use more than 900 million linked employer–employee records covering the entire formal workforce of Brazil to examine when cities provide upward mobility for the initially poor. We find that upward mobility for low-wage workers is strongest in workplaces that combine low-wage individuals with high-wage workers. This association is particularly pronounced in Brazil’s southern cities, where more complex industries include workers with a wider range of skills. The association is weaker in northern cities, where formal employment is dominated by the public sector.
Here is the paper by Radu Barza, Edward Glaeser, César A. Hidalgo, and Martina Viarengo. And here is a useful thread on the paper. This is one of the best and most important economics papers I have seen in the last few years.
Daddy’s Girl
Using Danish registry data, we study how managers’ gender attitudes shape gender inequality in the workplace by exploiting the birth of a daughter – as opposed to a son – as a plausibly exogenous shock to male managers’ gender attitudes. Comparing within-firm changes in women’s labor outcomes depending on the gender of the manager’s newborn child, we find that women’s relative earnings and employment increase by 4.4% and 2.9% respectively following the birth of the manager’s first daughter. These effects are driven by an increase in managers’ propensity to substitute male hires with female hires that have comparable education, hours worked, and earnings. Consistent with this substitution channel, we do not detect any significant effect on firm performance. Because these effects emerge rapidly and persist over time, we can rule out the need for prolonged exposure to gender issues or for personal incentives tied to improving conditions for their own daughters as prerequisites for managers to promote gender equality within their firms.
That is by Maddalena Ronchi and Nina Smith, forthcoming in Review of Economic Studies.
Data Centers and the Open Access Order
The US discussion over datacenters is depressing. Datacenters do not use a lot of water, they produce very useful outputs, they are not a blight on the landscape. All of this is obvious. But I don’t want to restate the obvious. What bothers me most about the discussion is that people seem to think this is or should be a collective decision. No.
We have a simple set of rules that everyone must follow. You buy land from someone willing to sell it. You contract for electricity. You hire workers who want the job. Your obligations to your local neighbors come from the same laws that govern everyone else. We do not ask what the land, electricity and labor is for. If you follow the rules, that is nobody’s business.
This is the distinction North, Wallis and Weingast make in Violence and Social Orders (paper here) between limited access orders or the natural state and open-access orders. For most of recorded history large-scale economic activity depended on access to political power. In the natural state, “people outside the coalition have only limited access to organizations, privileges, and valuable resources and activities.” The dominant coalition controlled entry into valuable activities and created rents by granting privileges.
An open access order works through general criteria. Organizational formation is “open to everyone who meets a set of minimal and impersonal criteria.” In economic life, the transition entails “the ability to create economic organizations at will, open entry and competition in many markets.”
The key word is impersonal. The same conditions apply regardless of who wants to build or whether public officials admire the proposed use. The state is not necessarily laissez-faire but its role ends once you have complied with the impersonal rules.
Now look at how a data center actually gets built. Rezoning, special use permits, comprehensive plan amendments, a negotiated “community benefits agreement” of school donations, fiber, soccer fields, and payments in lieu of taxes, public comment and then more public comment. These are not general rules. They are terms of admission negotiated with whoever holds the veto. Calling them community benefits doesn’t change the structure. Access to economic activity has become something that must be bargained for, argued for in the collective sphere, and paid for–with success determined by rents and political access. The natural state returns.
(The subsidies, by the way. are the same error wearing the other hat. A sales tax exemption written for datacenters and a county moratorium aimed at datacenters both replace a general rule with a judgment about whether this industry deserves to exist. An open access order offers neither special favors nor special burdens. It offers a rule.)
Opponents often complain that communities deserve more of a say. No, they do not. You did not vote on the bakery and the baker did not vote on you. That is the deal.
Datacenters happen to be where this is most visible today. Their size and novelty make them easy targets for vilification and rent extraction. But the big issue is not datacenters. It is whether building depends on following impersonal rules or on securing permission case by case from those who control access. The natural state was the human default for ten thousand years. The open access order that displaced it is the foundation of our prosperity and our political strength, and it is younger and more fragile than we like to think.
Do Minimum Wages Help Workers in Poor and Low-Income Families?
We provide the first direct estimates of the effects of minimum wages on low-wage workers in families at different points of the distribution of income-to-needs, using data from the Survey of Income and Program Participation, which oversamples low-income families. We find adverse – rather than beneficial – effects of minimum wages on the employment, hours, and earnings of initially-employed low-wage workers in poor and low-income families. Although we do not find a gradient indicating more adverse effects on the poorest low-wage workers, the adverse effects for poor and low-income low-wage workers help explain why minimum wages do not reduce poverty.
That is from a recent paper by David Neumark and Emma Wohl.
Democracy and Caeserism
In my 2015 post discussing Joseph Heath’s excellent book Enlightenment 2.0, I had this to say:
One of the reasons that I oppose the extension of democratic politics into every aspect of modern life is precisely that in trying to do too much, democracy delivers incoherence, gridlock and frustration, forces that eventually undermine its own legitimacy. I worry about democratic legitimacy because I see democracy as a check and balance on Leviathan (while Heath sees it as a check on government by experts).
The legislature has become a sideshow. But I worry, because the more Congress is held in contempt the greater the support for a bold executive that takes charge, makes decisions and gets things done. Under these pressures, executive power has grown not just in the United States but also in Canada and Great Britain (on this theme see F.H. Buckley’s The Once and Future King.) But for all its faults, the legislature and the rule of law are more conducive to liberty than the executive and the administrative state. Legislators are satisfied with reelection and a bit of pork but executives hunger for greatness and in so doing they promote the real dangers, idolatry, the centralization of power and war.
In short, I worry that the pathologies of democracy drive the demand not for rational, technocratic government but for Caesarism.
I should note that this was before Donald Trump was a Republican presidential contender, let alone a candidate for office.
Addendum: See also my review of Enlightenment 2.0. It has some good lines!
The propagandizing messages of markets and politics are also very different. Market messages are largely inclusive and cosmopolitan. Coca-Cola advertises “I’d Like to Buy the World a Coke” because they’d like the world to buy a Coke. Firms do try to build brand affiliation but they rarely do so by promoting hatred of their competitors. Pepsi doesn’t tell the Pepsi Generation that Coke drinkers are stealing their jobs and spitting on their gods.
Hat tip: @kingofthecoastt who recently tweeted about the original post.
The new agentic O-ring world
But because agents often require guidance or additional context as they move through their tasks, Sharma, 27, finds himself wanting to be available to them around the clock and forgoing a regular sleep schedule as a result. Until recently, he couldn’t monitor them remotely through a phone or smartwatch.
“The cost of the agents’ being blocked for eight hours is way too high,” he says. “They can be done with their work at any point of time, in the middle of the night.”
Founders have long put in punishing hours in the name of building the next big thing. But the growing capabilities of AI agents—and the speed at which the models powering them are evolving—give new meaning to working yourself to the bone…
“They just demand your attention,” he says. “Does it need anything? Can I help it in any way?”
…Pezaris, who lives in San Mateo, Calif., typically works from 7:30 a.m. to 2 a.m. He estimates Proxon, which employs six human developers, is operating 30 times faster than it would without agents. But agent work begets human work: Onboarding customers at a faster clip means needing to respond to more customer requests, for example.
There is also an agent FOMO multiplier effect. “Every minute that I’m not working, I’m missing out on not doing a week’s worth of work,” says Pezaris.
Here is more from Katherine Bindley at the WSJ. As I have been joking in some of my talks, we need to start taking bets on when the AI leisure dividend will arrive. It will, but not just yet…